Category: Generative AI

  • One person, one terminal, a team of AI agents: how I build software now

    One person, one terminal, a team of AI agents: how I build software now

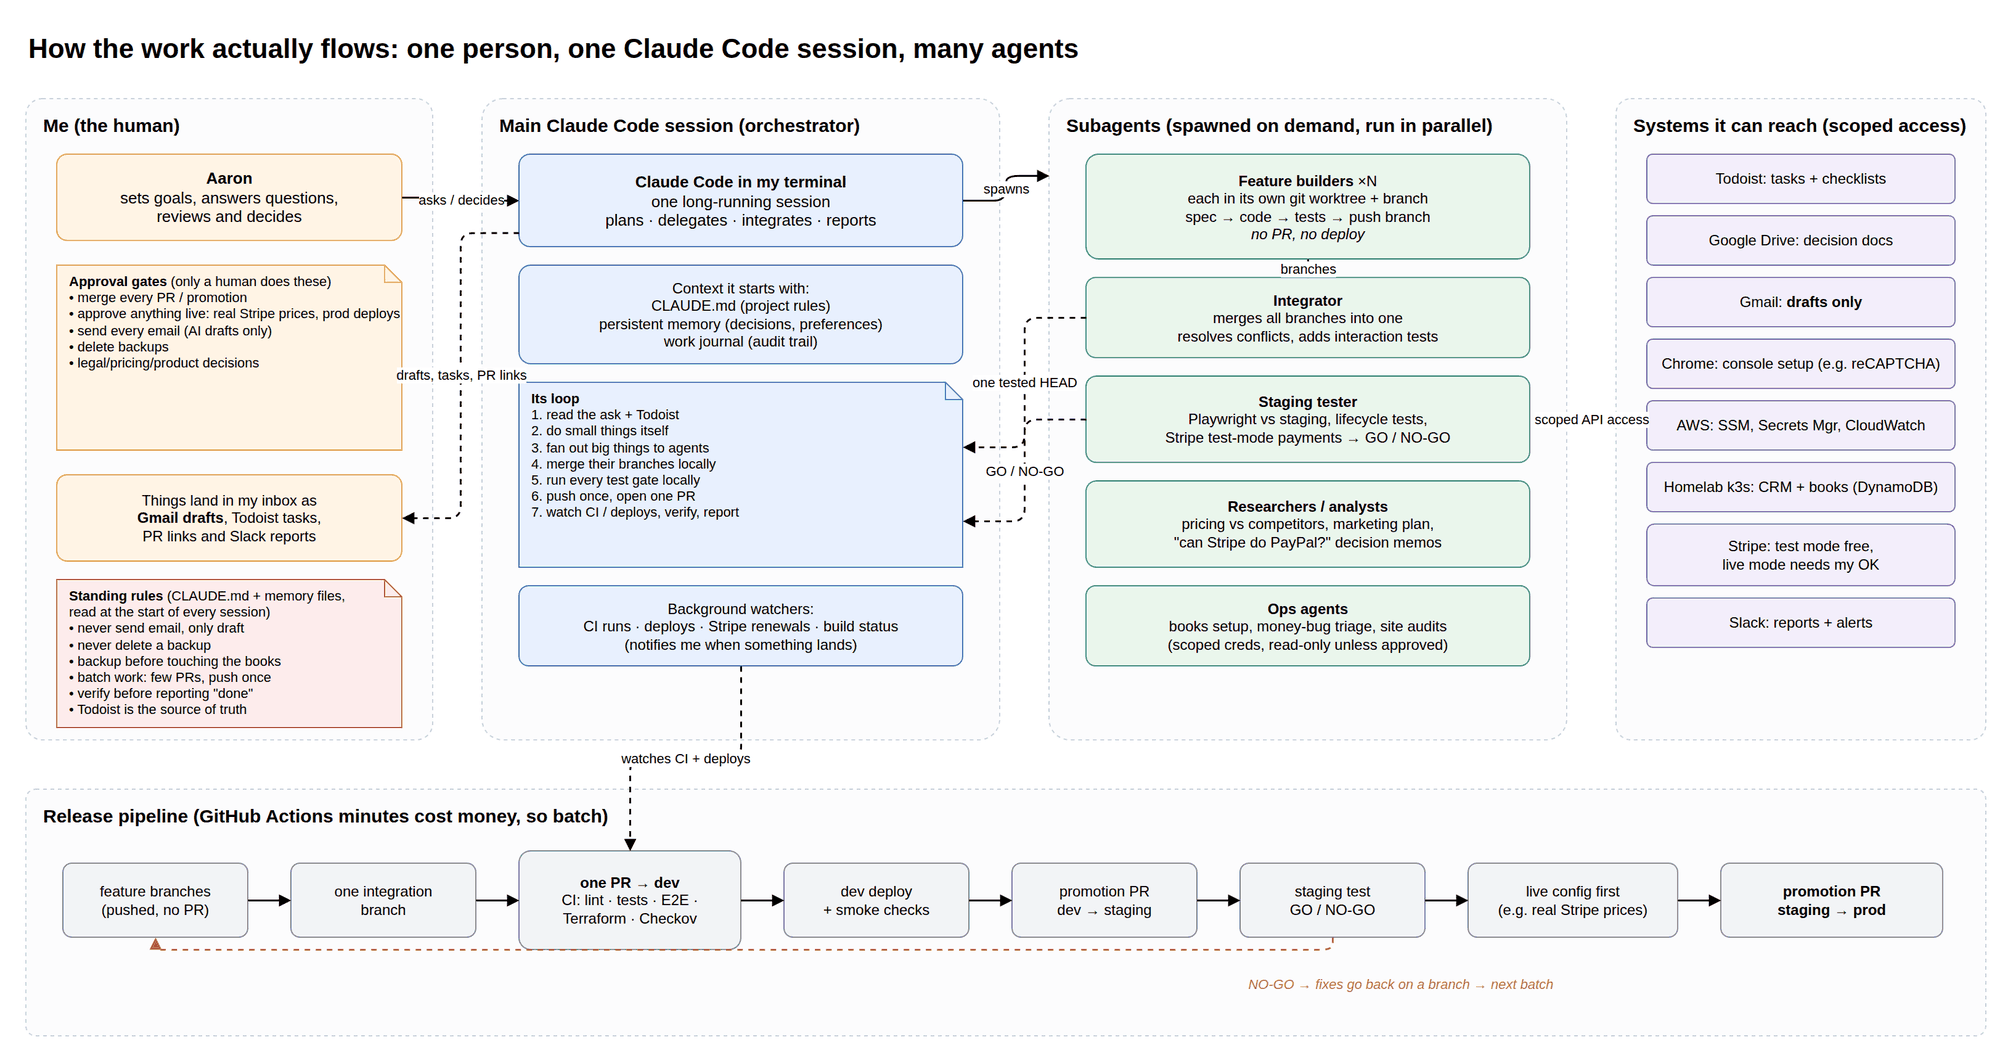
    Diagram: me, one Claude Code session, the subagents it spins up, the systems it can reach, and the batched release pipeline
    How the work flows: me, one Claude Code session, and the agents it spins up

    I build software in my free time. Lately that means my homelab: when there’s an app I’d normally pay for, I build my own version and run it at home. So far that’s a document archive that reads and files whatever I scan, a household finance app, a lockbox for the numbers a family shouldn’t keep in a spreadsheet, and a pile of smaller tools around them.

    I don’t write most of the code. One Claude Code session running in my terminal does. It acts like a project lead, handing pieces of the work to other AI agents and putting the results back together. My job is to make decisions and approve things.

    I’ve used the same setup for a product launch, for client work and for the homelab, and the rules turned out to be the same every time. Here’s how it’s set up, and the rules that keep it from going off the rails.

    The shape of it

    There are three layers:

    • Me. I set the goal, answer questions, and approve anything that touches real money, real data or other people.
    • One main session. This is the Claude Code instance I’m talking to. It reads the project’s rules, checks my task list, does small things itself, and hands big things off.
    • Subagents. When there’s real work to do, the main session spins up separate agents and runs them in parallel. Each gets a written brief, its own copy of the repo (a git worktree) and its own branch. When it’s done, it reports back.

    That’s one project. Once you have several, each project gets its own main session, and the sessions can message each other. That turned out to matter more than I expected. This week the homelab session settled on a new look for my dashboard. I told the session for a different project to use it. It asked the homelab session where the design lived, got back a written list of the colors, the layout and the choices it had decided against, and restyled every page of that project to match. The same day another session needed a list of to-dos filed for me. It asked the session that already had access to my task list, and that one filed them and reported back what it had created.

    I didn’t relay any of that. I said what I wanted, and the sessions worked out who knew what.

    Rule 1: batch the work, release once

    Left alone, every agent opens its own pull request, and every push kicks off a full build and test run. If you pay for build minutes, that adds up. Even if you don’t, five half-finished changes landing separately is five chances to break something.

    So the rule is:

    • Agents push branches but don’t open pull requests.
    • The main session merges them locally, runs the full test suite on my machine, and pushes once.
    • One pull request, one build, then one deploy.

    One thing to add: have it clean up after itself. Every agent’s private copy of the repo stays on disk until something removes it. When I finally looked at one project, there were 34 of them taking up 6.7 GB, nearly all for work that had already merged.

    Rule 2: the real thing is where the truth comes out

    Passing tests tell you the code does what the tests expect. They don’t tell you it works. The bugs that matter show up when someone, or some agent, uses the real thing the way a person would.

    My document archive is the best example I have. None of these came from a test. They came from using it:

    • A photographed statement came back a quarter unreadable. Three pages, one of them sideways. Reading each page more than once, and turning the sideways one, got that down to 6%.
    • The text reader was fighting itself. It sized itself for every processor in the machine while the app was only allowed one, so a page took 9.3 seconds when it should have taken 3.2. Run two scans at once and a page took so long that it timed out, and the document got filed with no text at all.
    • Uploads from a phone died at exactly 60 seconds. On a slow connection the upload simply took longer than a default timeout in front of the app. From the outside it looked like a flaky app. It was one setting.

    The dashboard had its own version of this. Its health widget showed a green dot for an app that had never been deployed, because a “page not found” answer counted as healthy. Nothing flagged it, because nothing was failing.

    So before anything is called done, an agent has to exercise it for real: click through the deployed site, upload the actual file, run the flow end to end with test data. Then it says go or no-go.

    Rule 3: the AI never makes the outward-facing decisions

    This one is non-negotiable, and it’s written into a rules file the AI reads at the start of every session:

    • It never sends email. It writes drafts into my Gmail, and I send them. (That rule exists because of a near miss where someone almost got the same email twice.)
    • It never deletes a backup. Only I do.
    • It backs up before it changes real data, and it logs the change in a work journal: what changed, why, the backup it took, and the numbers before and after.
    • Anything live needs my OK. It does a dry run, shows me exactly what will happen, and waits.
    • Some things it never sees. The lockbox holds passport and account numbers. Its rule is one line: none of it is ever given to an AI model.

    The same thinking applies to automation that runs when I’m not watching. I have a small script on my router that restarts the VPN connection when it goes slow. It has to see fifteen minutes of slowness before it acts, it checks that my internet isn’t the real problem, and after three restarts in a day it stops and tells me, because at that point restarting isn’t the fix. Something that can act by itself needs a point where it gives up and asks.

    Rule 4: make it check its own claims

    AI is confident. That’s not the same as right, and the fix is to check claims against evidence instead of asking how sure it is.

    The document archive taught me this one too. It uses a model to read each document and pull out the date, the sender and the amount. On a handwritten childcare invoice it reported 90% confidence, and every value was invented. It read “$20” as “$ZO” and gave a service period starting on February 29 in a year that doesn’t have one. Its confidence was only ever about which category the document belonged in.

    So the archive doesn’t go by the model’s confidence anymore. A document gets flagged for me to review if a value it pulled out doesn’t actually appear in the text, if a date can’t be true, or if the scan itself was hard to read. Plain checks, with no model involved.

    The same goes for what it writes about its own work. My homelab notes said an old service had been removed from every build pipeline. When an agent checked, 12 pipelines still loaded it. The dashboard listed which machine ran which app, and three of four were wrong. Now the rule is to check the running system, not the notes, and to fix the notes when they disagree.

    Rule 5: write decisions down where people will find them

    Small decisions pile up fast. If they only live in a chat, the next session starts from zero and makes a different call.

    • Every decision becomes a task or a note in Todoist, which is my source of truth.
    • Rules that should hold next time go into the project’s rules file, with the reason. “Never delete a backup” is a rule. The story of what happened the one time it did is what makes the next session take it seriously.
    • The homelab keeps a map of what exists and a short list of how new things get built there, so a new app starts from the same conventions as the last one.
    • At the end of a long day, I have the main session go through the task list and close what shipped, with notes on where each thing landed.

    What I’d tell you if you try this

    • Keep one session in charge of each project. One orchestrator with a clear picture beats five independent chats stepping on each other.
    • Give agents narrow briefs and their own branches. Parallel work is great until two agents edit the same file. Separate copies plus one integration step fixes that.
    • Release in batches. Merge locally, test once, push once.
    • Trust the real thing, not green tests. A real scan from a real phone found what the tests didn’t.
    • Check claims against evidence. That includes the AI’s confidence and its own notes.
    • Keep the outward-facing actions for yourself. Email, live changes, production deploys and deleting anything stay with a human.

    It isn’t hands-off. I make a lot of calls. But I spend my time deciding instead of typing, and that’s the trade I want.

    If you have questions about the setup, feel free to reach out!
    Don’t miss an update

  • Tools for a better fantasy football team and Week 2 results

    Tools for a better fantasy football team and Week 2 results

    This is a more technical document about how the tools work for my Fantasy Football agent in conjunction with https://gridirondata.com. At the top level, the coach is a Strands based AI agent that runs Anthropic Claude Sonnet 5 on Amazon Bedrock. The agent knows about my roster, and other teams rosters in my league which is hosted on ESPN’s Fantasy Football platform.

    Lineup Tools:

    • Optimize Lineup: Builds the best starting lineup for a team for any given week. It fills every slot with the highest projected eligible player. Projects are adjusted for injury designation and takes into account players who are on a bye week.
    • Start or sit advice: Compares the best lineup with the teams current starters and says exactly who to start or who to bench OR that no change is needed

    Player Research:

    • Analyze player: A full look at one player for one week: projection, injury status, opponent and bye (from the NFL schedule), boom/bust profile and recent news.
    • Compare players: Compares two players side by side for a week and recommends one to start.
    • Player boom or bust: A player’s season-long deviation profile, showing whether they usually beat or miss their projections and how steady their floor is.
    • Player matchup: How a player has scored against a given opponent in the past. If no opponent is given, it looks one up from the schedule.
    • Player news: Recent headlines for a player (injury, transaction, role), tagged by impact.

    Waivers & Streaming

    • Find waiver targets: Ranks free agents (projected players on no league roster) by how much they would improve on your weakest starter at their position, not just by raw projection
    • Stream defense: Compares your D/ST with the best free-agent defenses: projection, this week’s and next week’s opponent, history against the opponent, and whether streaming is worth it.

    All of these tools have more complex technical code that dictates exactly how they work and access the API. There are also various scoring rules for injured or questionable players. This might result in their projects lowering allowing for a bench player to get the nod to start for the week.

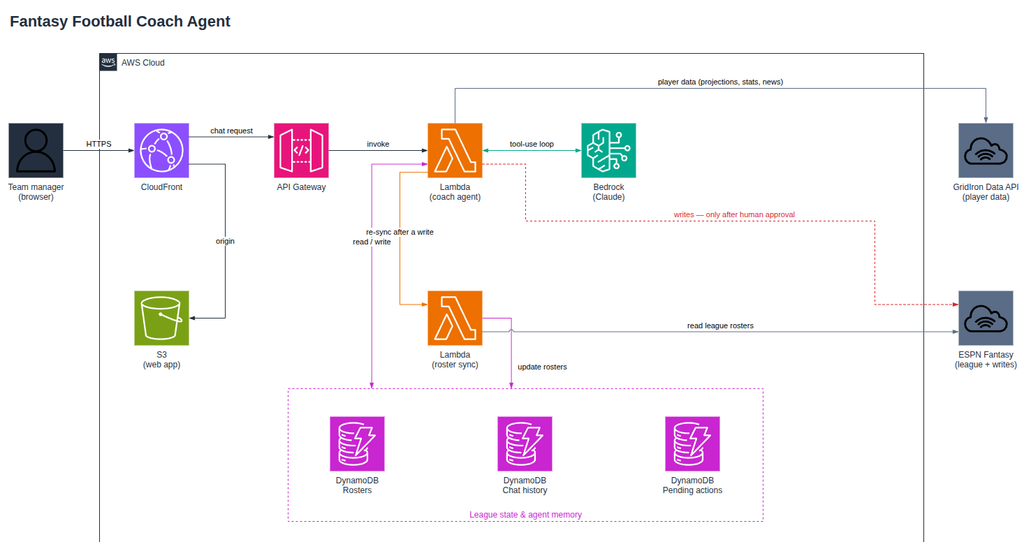
    The architecture is a pretty straightforward serverless design that relies on Cloudfront and S3 for frontend delivery and an API gateway to handle the chat.

    Fantasy Football Agent Architecture

    I use DynamoDB to manage our chat state as well as rosters for every team in the league. Bedrock is the AI layer where Sonnet runs.

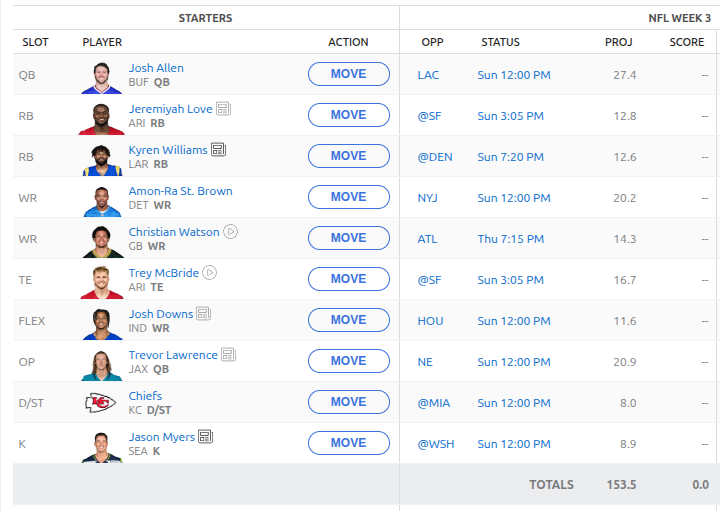
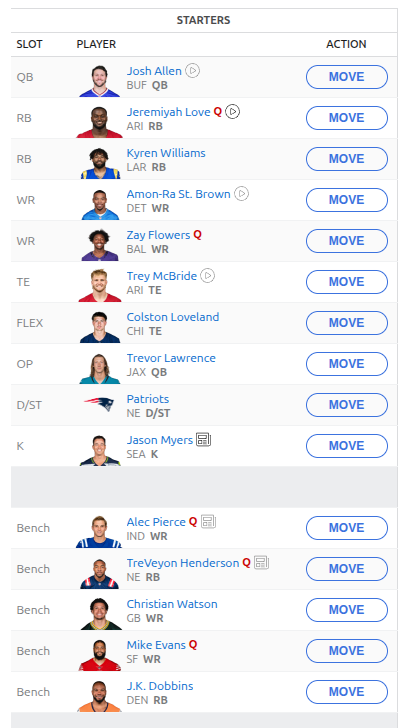
    Anyway, enough nerd talk. Here is the current roster for week 3:

    Notable changes are adding the Chiefs defense against a horrific Miami team. Adding in Josh Downs due to injuries across other wide receivers. I personally would have liked to see the AI select a running back here but it was adamant that Josh Downs was the move.

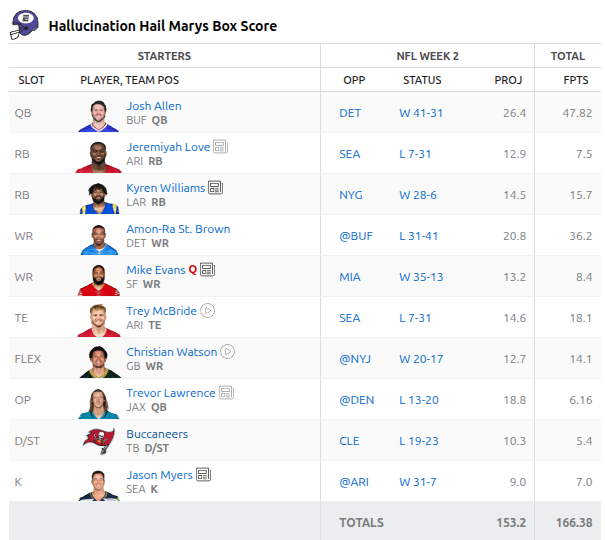
    Another dominate week for us. We are currently in first place in the league. Some players were busts though:

    Jeremiyah Love simply didn’t get the ball when I was watching the Cardinals play. I have no idea what happened with Trevor Lawrence. His receivers couldn’t catch or something and apparently Cleveland figured out how to beat up the Buccaneers. Mike Evans went out with injury but dominate performances from Josh Allen and Amon-Ra St. Brown carried us to victory again.

    See you all next week for another update. If you want me to expand on any topic here feel free to reach out!
    Don’t miss an update

  • Fantasy Football & AI – Week 1 – Season 2

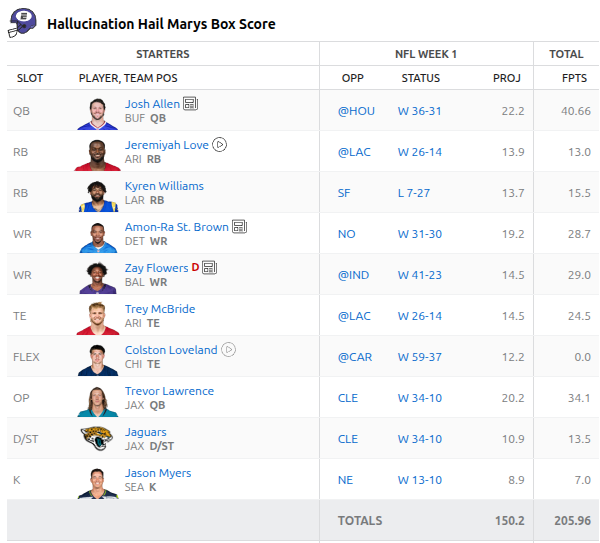
    What a start to the season. HUGE totals from a bunch of a players and one bust. We are starting off the season with a big win. Josh Allen came in big in his season opener, Zay Flowers exited with injury but not before putting up 29 points. Amon Ra St. Brown also put up almost 29 points for us.

    Weirdly, Colston Loveland put up 0 points. I didn’t get to watch the game but his stat line was not great.

    Also, let me introduce you to the “Hallucination Hail Marys”. A fitting name for a team driven by data and AI.

    Week 1 projections and finals

    So, I’m still using https://gridirondata.com as the backend for the AI. I’ve upgraded models to be Claude Haiku 4.5 and of course i’ve kept the personality to be Dan Campbell.

    I’ve updated the interface to be a bit more modern. I’ve also introduced the ability for the AI to be able to update the ESPN roster directly. I’ll go into a full breakdown of all the tools that the agent has to accomplish a winning season in another post.

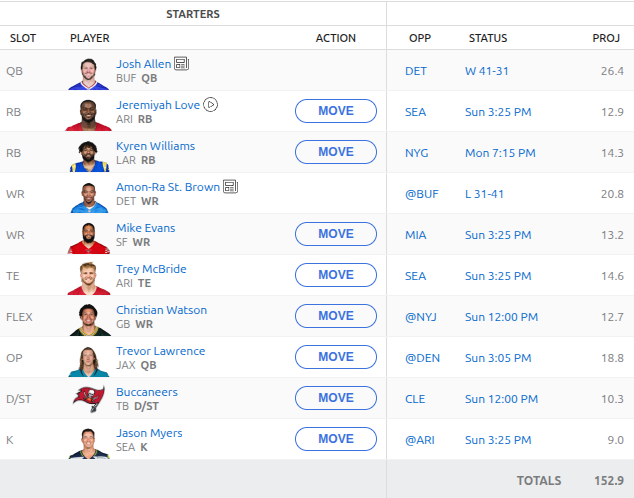
    For week 2 we’re mostly keeping the same roster. One thing to note is that we swapped defenses. Based on the Brown’s abysmal performance last week, Coach Campbell suggested we grab the Bucanneer’s which I think could be a great move OR the Browns will rally and it won’t work out. I’ve hid some of the actuals because the Bills and Lions played Thursday night. but, its shaping up to be a good week!

    Week 2 projections and lineup

    See you all next week! If there is anything you want me to go more in depth on be sure to reach out!

    Don’t miss an update

  • We’re BACK – Fantasy Football 2026-27

    Back by literally no demand will be my Fantasy Football series! New team, new draft agent, new tech to support the team. If you are new here, last year I did a whole series about using AI to manage my Fantasy Football team. I was even . interviewed about it.

    During the NFL offseason I retooled the drafting agent. Some highlights:

    1. New data backbone using https://gridirondata.com that has historical season context, player news, and season actuals (once the season starts)
    2. Newer AI models – Last year I used Anthropic’s Haiku 3.5 model. This year, we have Haiku 4.5. The model reasoning is now more roster aware in the sense that it wants to add starters first and then focus on bench seats.
    3. A real GUI – last years draft was done all via CLI. This year I have a full web interface for drafting, seeing the AI recommendations as well as “best available” players.

    I’m still retooling the “Coach” but don’t worry, I will still force the AI to adopt a Dan Campbell persona.

    So, I present to you for the first time… The Hallucination Hail Mary’s!

    If you think we are going to win the league this year comment below. Otherwise just let me know what you think!

  • AWS Transform is the wrong tool for the job you actually have

    AWS Transform is the wrong tool for the job you actually have

    First off, I want to say I love Amazon Web Services, Kiro, and any effort that makes migrations from legacy to modern tech stacks. But, I also like the counter argument.

    AWS launched AWS Transform as “a collaborative enterprise IT transformation workbench powered by expert agents.” It promises to modernize your .NET apps 5x faster, shrink mainframe projects from “years to months,” and automate VMware migrations end to end. The marketing page claims 4.5 billion lines of code analyzed and 1.69 million hours of manual effort saved in the last twelve months.


    I’ve read the pitch. I’ve watched a couple of demos. I think most teams considering it should walk away, and I want to explain why —
    and what to do instead.

    What AWS Transform actual is

    Strip the agentic-AI gloss off and Transform is three things bundled together:

    1. A discovery and assessment layer that scans your existing estate (codebases, VMs, dependencies).
    2. A set of pre-built “agents” that perform specific transformations: .NET Framework → .NET on Linux, COBOL → Java, VMware →
      EC2, Java 8 → Java 21, and so on.
    3. A workbench (web console plus Kiro IDE integration) where humans review and approve agent output.

    It’s a continuation of a lineage: Migration Hub, MGN, App2Container, the old Microsoft Workloads tooling, the original CodeWhisperer transformation features. AWS keeps reshuffling these into new umbrella brands. Transform is the 2026 wrapper.

    That history matters, because it tells you something about the half-life of the product you’re betting on.

    My core objection: the output is shaped like AWS

    When you let an agent translate a COBOL batch job into Java, or a .NET Framework service into .NET on Linux, you don’t just get “modern code.” You get code that looks the way AWS’s agent decided modern code should look. The data access patterns it picks, the logging conventions, the way it splits modules, the runtime targets it assumes — all of that is now baked into your codebase, and none of it was a decision your team made.


    This is fine if you’re a hands-off shop that’s going to run whatever comes out the other end. It’s a disaster if you intend to own and evolve the system afterward. You will spend the next three years asking “why is it like this?” and the answer will be “because an agent decided in May 2026.”


    There’s a deeper version of this problem with mainframe and VMware work. The agent doesn’t just translate code — it picks the AWS-native destination. Step Functions instead of your existing scheduler. DynamoDB instead of “let’s think about whether this data actually fits a KV store.” Network conversion that assumes you want VPC-native everything. These are not neutral technical choices; they are commercial decisions made on AWS’s behalf, inside your repo.

    The metrics are a vendor-pitch, not a forecast

    “5x faster.” “70% lower operating costs.” “Years to months.”


    Every modernization vendor has said versions of these numbers for twenty years. They are real for the case study they came from. They are almost never what you will personally experience, because:

    • The 70% cost reduction usually compares licensed Windows Server + SQL Server Standard on owned hardware against Linux +
      an open-source database on Graviton. Most of the savings come from switching the license model, not from anything
      Transform does. You can capture that yourself.
    • The “5x faster” number is measured against a baseline of “team that has never done this before, doing it manually.” If your
      team has done a .NET migration once, your real multiplier is closer to 1.5x.
    • The mainframe-to-Java case studies almost always involve workloads that were already partially decomposed. The genuinely
      tangled mainframes the ones where modernization is actually hard are not the ones that ship as case studies.

    If a vendor’s headline metric needs four asterisks to be accurate, it isn’t really a metric.

    Modernization that skips understanding is just translation

    The thing I dislike most about Transform, and about agentic modernization in general, is that it lets you finish a project without anyone on your team understanding what they now own.


    When a senior engineer spends six months untangling a COBOL system to port it, the porting is half the value. The other half is that, at the end, someone in the building understands the system. They know where the landmines are. They can answer questions in incident review. They can tell product what’s safe to change.

    If an agent does the port, you get code on the other side and an organization that is no smarter than it was before. Worse: you now
    have a Java codebase that nobody wrote and nobody fully grasps, sitting on top of business logic nobody re-derived. The first production incident will be ugly.

    This is the same complaint people have about outsourced rewrites, and it applies cleanly to agent-driven ones.

    The Kiro and tooling lock-in

    Transform leans on Kiro, AWS’s IDE, with “pre-built playbooks.” Adopting Transform meaningfully means asking your engineers to learn Kiro, to work inside AWS’s review workflow, and to accept handoffs in a format that’s optimized for AWS’s agents to re-enter later.


    That’s a real switching cost. Two years from now, when AWS rebrands Transform into whatever comes next, those playbooks and that workflow knowledge depreciate fast.

    What to do instead

    I’m not arguing for “do nothing” or “stay on the mainframe forever.” Modernization is often the right call. But the right shape is almost always:

    1. Do the assessment yourself, or with a consultancy you’d hire anyway. The discovery piece of Transform is the least controversial part — but it’s also the part you most want to own. Knowing your own estate is a permanent capability. Renting it from an agent is not.
    2. Use general-purpose coding agents under human direction, not vertical modernization agents. Claude Code, Cursor, Copilot in agent mode these are genuinely useful for the grunt work of a migration (rewriting a thousand similar files, fixing a known refactor pattern, translating tests). The difference is that your engineer is driving, deciding the target architecture, and reading the output. The agent is a force multiplier, not a contractor.
    3. Small wins, not big-bang. Pick the highest-pain module. Modernize it. Run it alongside the old system. Cut over. Repeat. This is slower on paper than “let the agent do it all,” but it produces a team that understands the new system at each step. And you can stop whenever the remaining legacy stops costing you money — which, for a lot of mainframe workloads, is the honest answer.
    4. Separate the license/runtime change from the architecture change. If most of your savings come from leaving Windows + SQL Server, do that migration as its own project. Don’t let it get bundled with a re-architecture, because the re-architecture is where the risk lives and you want it isolated.
    5. Be honest about workloads that shouldn’t move. Some legacy systems are stable, cheap to run, and changed once a quarter. Modernizing them is a status project, not a value project. Transform’s marketing will never tell you this; a good architect will.

    TLDR:

    AWS Transform is well-engineered. The agents work. The demos are real. None of that is the question.


    The question is whether you want to end a multi-year modernization with a codebase shaped by AWS’s opinions, a team that didn’t learn the system, and a tooling dependency on a product line AWS will rename in two years.

    For most teams I’ve worked with, the answer is no. Use agents — yours, under your control — to make your own engineers faster. Keep the architectural decisions in the building. Skip the workbench

    Questions? Let me know.

    Don’t miss an update

  • Building a CloudWatch AI Agent – Architecture & Lessons Learned

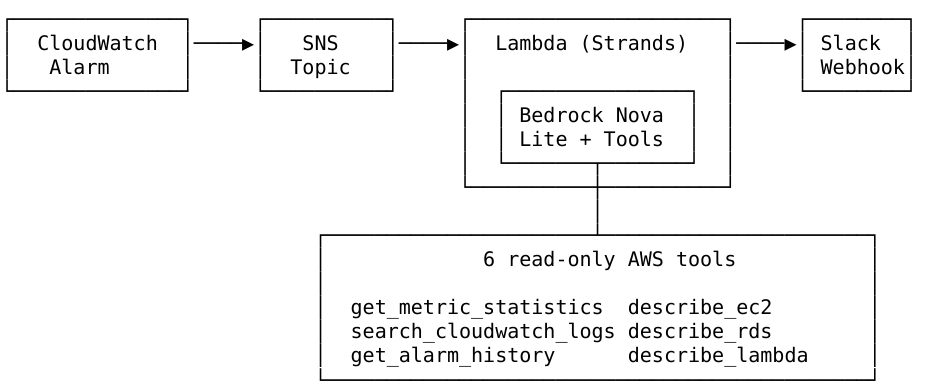
    I started off this project as a simple AI agent that would help me troubleshoot issues within my AWS environments. If we wrap up an LLM inside of a Lambda function and then feed the alarms to it, have Amazon Nova Lite interpret the alarm and then give me some troubleshooting steps.

    I chose Nova Lite because of its cost and and it is quite preformant when troubleshooting AWS resources. The overall time from alarm to Slack notification was between 12 and 20 seconds.

    When I first created this solution I wanted to sell it as a monthly service. The user would deploy the routing infrastructure into their own account and I would host the LLM layer. I priced this cheap. $5 per month. That’s it.

    The problem was that nobody was interested.

    As I continued to promote the product the constant feedback was that nobody wanted to send any data to a 3rd party account. I refactored the architecture so that the LLM functionality would live in their account and the subscription would cover maintenance and support.

    Still no interest.

    At the end of the day, I created something before validating that someone actually wanted the solution. While it saves time in troubleshooting it lacks the ability to solve the problem. A human engineer might save some time discovering the root cause but they still have to fix the issue.

    I still use this setup in my personal account. I made the repository open source so that if anyone wants to utilize it they can. Maybe someone will find it useful!

    Check it out on my other website

    Don’t miss an update

  • An agentic Kanban Workflow

    An agentic Kanban Workflow

    I had this idea the other day and started building it into a project I’m working on. We all hate Jira but, the idea of Kanban is still a useful way to track projects.

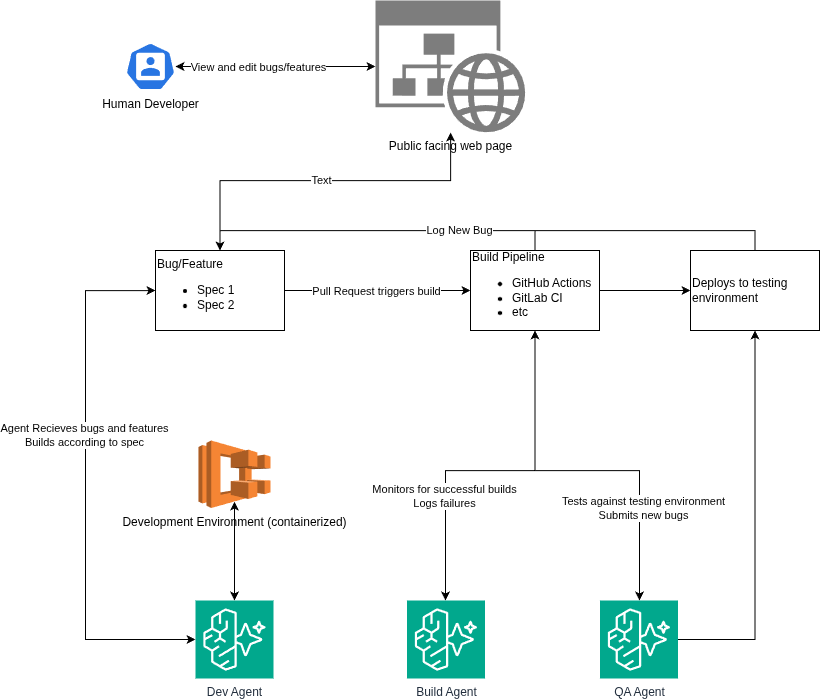
    As we think about this in the AI era we could easily integrate the Jira MCP into a workflow but, once again we hate Jira. So that led me down a path of reinventing the wheel, mostly for my own purposes. I came up with this simple diagram:

    We will forever want to keep a human in the loop so a web interface is still likely necessary. However, a text based interface could also be cool…. Maybe in the future!

    What we end up with is a system of three agents:

    1. Developer agent – this agent writes and builds code in a sandboxed container based on specs written either by a human or by bugs found by the QA agent
    2. Build Agent – This agent monitors our build pipelines and if there is a failure it diagnosis why and opens a bug accordingly for the developer agent to fix
    3. QA Agent – Arguably the most important agent. This one will execute testing as close to simulating a human interaction with the software as possible. Upon finding bugs it would be able to log them back into the Kanban for the developer agent.

    Now we have a full DevOps life cycle with three agents. If I build this out, I become the user who is simply entering specs as features or bugs for the developer agent to work through. The code is still stored inside of some git based repository, build failures can utilize my already coded Build Failure Agent. Claude Code or Codex could function as the developer agent or we could run the whole thing on AWS Bedrock.

    Proof of concept coming some day when I have time!

    Don’t miss an update

  • The state of SEOScoreAPI – An OpenClaw Project

    The state of SEOScoreAPI – An OpenClaw Project

    If you remember, I did an experiment with OpenClaw. I let it have access to build anything it wanted with a single EC2 instance. It built https://seoscoreapi.com which is a fantastic tool for checking the status of your websites SEO.

    Initially I thought I would scrap the project and just let the domain expire. But I started doing some manual promotion after OpenClaw spent over $200 and got the first paid user! Since then I’ve put a few hours a day promoting and adding some features.

    What’s New

    The last few months have been the most productive stretch since launch. Here’s what shipped:

    ADA Accessibility Audits

    This one came from watching the news. ADA website lawsuits hit over 4,000 in 2025 and they’re still climbing. Small businesses, e-commerce sites, local restaurants — everyone’s a target.

    We built a full WCAG 2.1 AA compliance endpoint that injects axe-core (the industry-standard accessibility engine) into a headless browser and scans the rendered page. It returns a compliance score, a lawsuit risk assessment, category breakdowns across 10 areas (color contrast, forms, keyboard navigation, ARIA, etc.), and specific fix suggestions for every violation.

    We ran it on our own site first. Scored a 71. Found contrast issues, links that weren’t distinguishable from body text, a misused aside element. Fixed everything. Now we score 100. That’s the point — even developers who care about accessibility miss things.

    Available on all paid plans. Starter gets 5/month, Ultra gets 500.

    GEO (Generative Engine Optimization)

    Traditional SEO gets you into Google. GEO gets you into ChatGPT, Claude, Perplexity, and every RAG pipeline pulling from the web.

    The GEO audit checks 26 factors across four categories: crawl accessibility, structural markup, content extractability, and AI discoverability. It answers questions like: Do you have an llms.txt file? Is your content chunked in a way that RAG systems can ingest? Do you have freshness signals? Are AI crawlers even allowed in your robots.txt?

    This is becoming more relevant every month. Traffic from AI systems is growing and most sites aren’t optimized for it at all.

    Competitive Audits

    You can now audit your site against competitors in a single request. The response shows a side-by-side comparison with score differentials, category-by-category breakdowns, and which specific checks you’re winning or losing on. Useful for agencies pitching prospects and for anyone doing competitive analysis.

    What’s Next

    Honestly I’m not sure. I would love to get more people using the service. Possibly some more integrations, a WordPress plugin?

    Try It

    If you’ve read this far, go audit your site: seoscoreapi.com

    The demo on the homepage doesn’t require a signup. Type in your URL, see your score, read the priorities list. If you want API access, the free tier takes 30 seconds to set up — just an email and a verification code.

    If you’re a developer, the docs have everything. Python and Node.js SDKs are on PyPI and npm. The GitHub Action is at SeoScoreAPI/seo-audit-action.

    If you have questions or feedback, I’m at aaron@seoscoreapi.com.

  • Evolution of my build failure agent

    Evolution of my build failure agent

    I’ve written in the past about troubleshooting build pipelines with AI. While all of this is a great step in speeding up your development and reducing the amount of troubleshooting the DevOps team needs to do in the enterprise, it is NOT the end goal.

    The end goal would be to have the AI fix the problem for you.

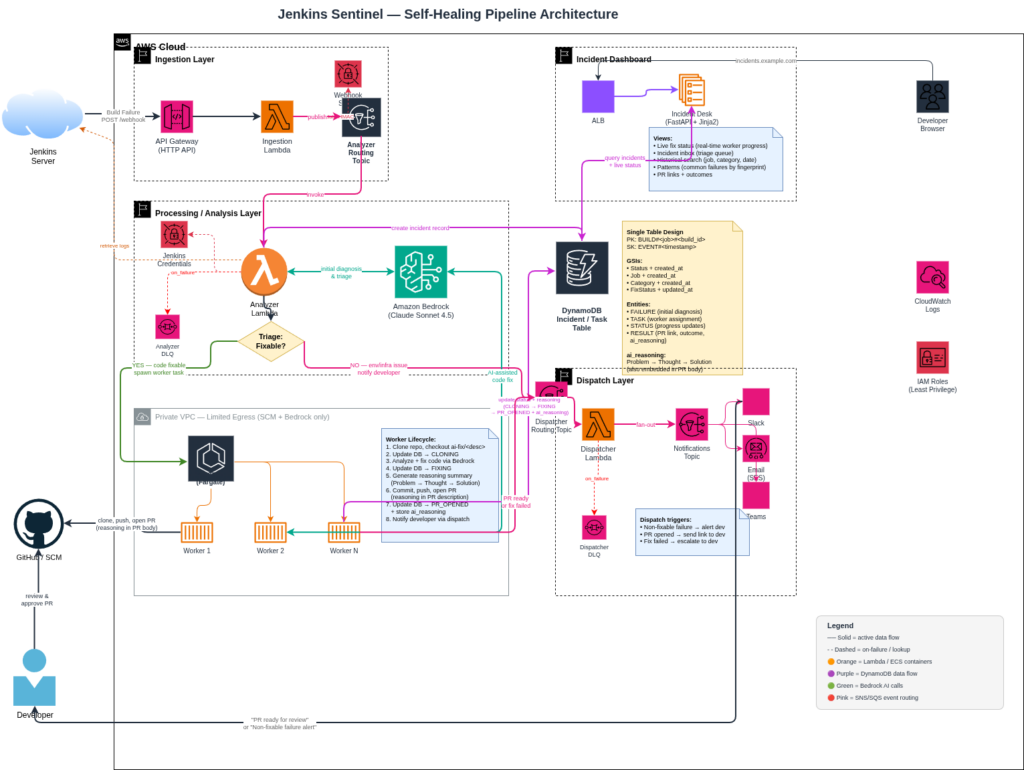
    I’m rebranding my Jenkins Sentinel to just be Sentinel. This workflow allows you to automate remediation for your pipelines while still retaining human in the loop security.

    The other primary feature is storing your build failures and remediations in a database that you can view, update, analyze for custom model training.

    Originally we had the dispatch layer that would notify us of build failures and possible resolutions. The new addition is the cluster of “workers”. Running on AWS Fargate, this team of developers works with the LLM on Bedrock to resolve the failure.

    1. The task spins up in the cluster
    2. The build logs identify the repository and branch
    3. The repository is cloned, and branch checked out
    4. The code fix is implemented
    5. The task generates its reasoning and updates the database accordingly
    6. Code is committed to a new branch and a pull request is opened.
    7. The task cleans up and shuts down

    Dispatch still remains the same and the developer is notified accordingly. I need to implement developer specific notifications so that channels are not flooded or email lists abused.

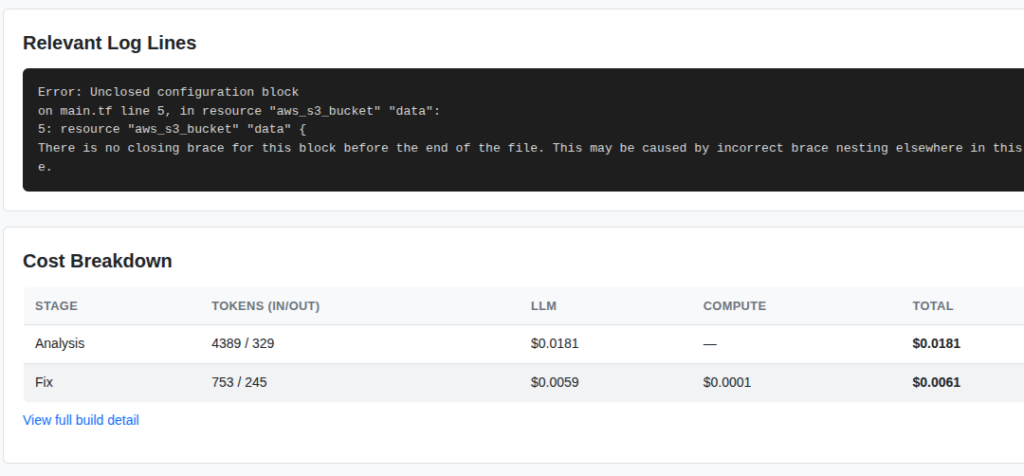
    The other major thing I wanted to see was the cost per fix.

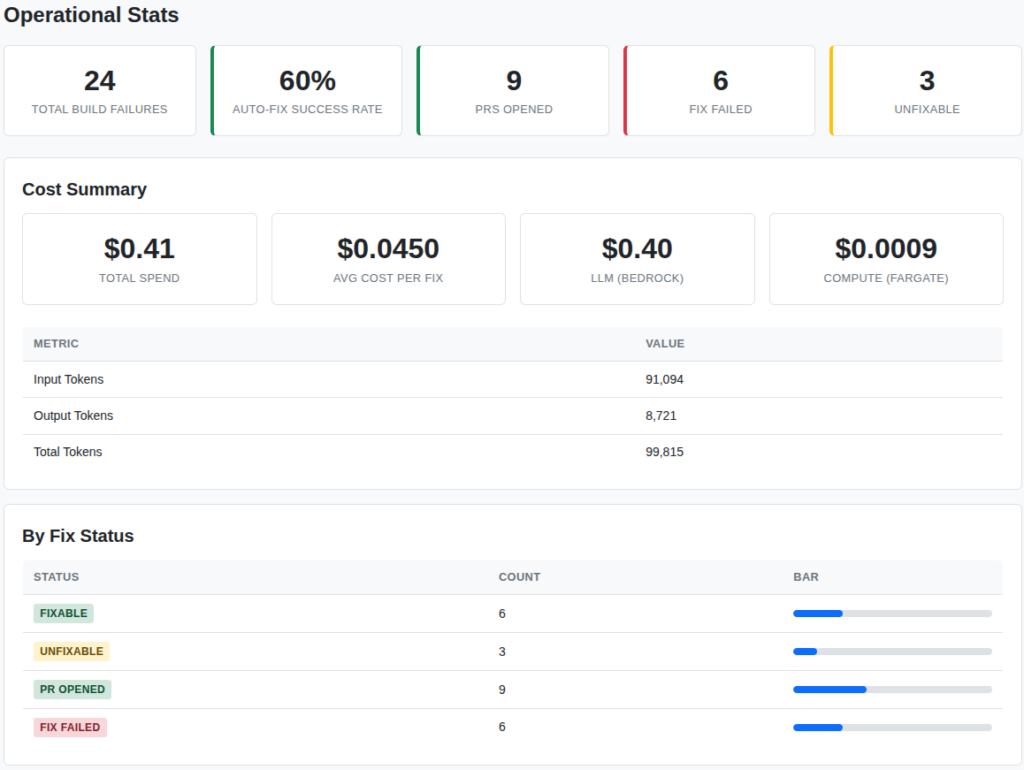
    This screenshot is from the dashboard which shows the compute spend and the LLM spend. For this simple Terraform fix you can see the was a little around $0.02. Assuming your code bases are more complex this value could increase proportionally.

    I also included a stats page which shows the totals for the entire organization.

    This is all real data from my testing project. The build agent is successfully troubleshooting pipelines for:

    • Python
    • Terraform
    • Java
    • Typescript
    • Docker
    • Kubernetes
    • Go
    • Cloudformation

    I plan to continue to add more supported platforms and languages as time allows. The other major integration that I am working on is support for GitHub Actions. Once I complete that integration and put this into all of my pipelines I expect that my troubleshooting and development time will decrease rapidly.

    Other future plans include:

    • Ingestion of bugs through sources like Jira, ToDoist (my favorite), or another ticketing system.
    • Discord Dispatching
    • Teams Dispatching – although this is really hard to develop for without a paid account
    • Custom model – using the build failure data to train a model

    Anyway, this project has been super fun. If you want to implement it on your own infrastructure feel free to reach out!
    Don’t miss an update

    PS: the featured image was generated and setup through my Nano Banana WordPress plugin

  • Fantasy Football and AI – The next season

    Fantasy Football and AI – The next season

    If you aren’t familiar with my Fantasy Football series from last year, I built an AI assisted drafting agent based on data I collected from previous seasons. I then iterated over that setup to build an in season coach that determined my line up each week. AI and I did pretty well but ultimately we are still chasing the championship.

    So now what? How do I improve the system? Well, I started over.

    This off season I took all of the stats I could get from 2020-2025 seasons. I restructured my database and moved it all to my local home lab. The purpose of this was to be able to cost effectively train, re-train, throwaway, and train again multiple models using multiple strategies for each position until I could accurately predict the results of the 2025 season.

    The result is a CatBoost and LightGBM system of models that has the following features:

    • Rolling Stats – 3, 5, 8 week rolling average of fantasy points
    • Vegas lines – spread, over/under, team implied total, implied win probabilty
    • Next Gen Stats: snap counts, target share, CPOE, rush yards over expected
    • Play-by-play: EPA per play, weighted opportunity share, red zone target share, goal-line carry share
    • Defensive matchup: rolling 5-week EPA allowed by the opposing defense at each position
    • Injury status: game designation, practice participation, teammate injuries
    • Schedule context: home/away, dome/outdoor, rest days, primetime

    I tested XGBoost, LightGBM, CatBoost, NGBoost, LSTM, and Transformer architectures. CatBoost + LightGBM ensemble won — the gradient boosting models crushed the deep learning approaches on tabular data (MAE 2.95 vs 4.68 for the LSTM).

    Using this, I then build a brand new draft simulator that tests various selection strategies based on position in the draft, draft type, and number of teams.

    The infrastructure is setup for next season. I’ll be going into more detail on each aspect of this setup throughout the off season. If you are interested in using the model feel free to reach out!